You’re staring at a blank screen, trying to describe a database schema to an AI. You want it to be robust, scalable, and secure. So you fire up the most expensive, powerful model you have access to-Claude Opus or GPT-4-and ask it to generate some basic CRUD endpoints for a user profile. Three weeks later, your invoice arrives, and you realize you just spent $800 having a premium brain write code that a budget model could have handled in seconds. This is the trap of vibe coding: assuming bigger is always better.
Vibe coding isn’t about writing every line yourself; it’s about describing intent and letting AI handle the implementation. But as we move deeper into 2026, the "one-size-fits-all" approach is dead. The market has shifted from single-model reliance to sophisticated tiered systems. If you’re still using one model for everything, you’re likely wasting money and time. Let’s break down how to actually choose between Claude, GPT-4, and Gemini without losing your mind-or your budget.
Understanding the Vibe Coding Paradigm
First, let’s get on the same page about what vibe coding actually is. It’s not just autocomplete on steroids. It’s a workflow where you provide high-level conceptual descriptions-the "vibes"-and the AI generates the functional code. This paradigm exploded in popularity between 2024 and 2025 as large language models crossed the threshold of being genuinely useful for complex software tasks.
The core problem developers face now isn’t whether AI can code; it’s which AI should do which job. According to recent analyses by Vooster AI, strategic model selection can reduce development costs by up to 37% while maintaining quality. That’s huge. Yet, many teams ignore this, treating their AI assistant like a hammer when they need a screwdriver, a wrench, and a laser level.
This shift requires a new skill: model orchestration. You need to know the strengths and weaknesses of each major player. Currently, the big three are Anthropic’s Claude series, OpenAI’s GPT-4 series, and Google’s Gemini series. Each has carved out specific niches in the development lifecycle.
Claude Opus: The Architect’s Choice
Claude Opus is Anthropic's flagship model designed for complex reasoning and long-context understanding. Released in late 2025, the Opus 3.5 version (with Sonnet 4.5 following in early 2026) features a massive 1.2 million token context window. This isn't just a spec sheet number; it means you can feed the entire codebase into the model and ask questions about architectural dependencies without losing track of the details.
Where Claude shines is in critical design tasks. Think database schemas, system architecture, and security-sensitive logic. In HumanEval coding benchmarks, Claude Opus 3.5 hits an impressive 87.4% accuracy. More importantly, it excels at chain-of-thought reasoning. When designing a user permission system, Claude might process 14.7 logical steps per schema, whereas competitors often skip steps to save tokens. This thoroughness prevents bugs that only appear under load.
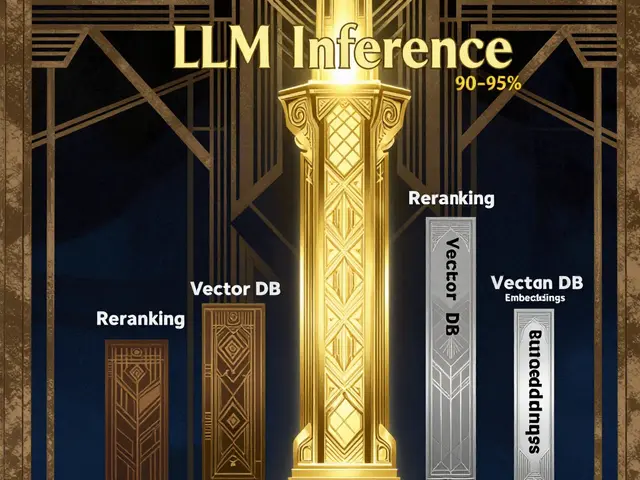
However, this precision comes at a cost. Using Opus for simple tasks is inefficient. Dr. Elena Rodriguez from MIT noted that using Opus for basic CRUD operations results in a 63% cost inefficiency. If you’re generating a simple HTML button or a basic API endpoint, you’re paying for horsepower you don’t need. Use Claude when the stakes are high: initial project setup, complex business logic, or reviewing another model’s output for blind spots.
GPT-4 Turbo: The Stability Anchor
GPT-4 Turbo is OpenAI's versatile model known for balanced performance and strong architectural decision-making. With its 128K token context window, it sits comfortably between the massive context of Claude and the speed-focused nature of smaller models. GPT-4 Turbo achieves 82.1% on HumanEval, but its real value lies in its consistency.
GPT-4 is often described as having a "stability orientation." It rarely hallucinates wildly compared to some newer, more experimental models. For architectural decisions, GitHub’s data shows GPT-4 leads with 89% accuracy, outperforming both Claude Sonnet and Gemini in this specific area. This makes it ideal for general development phases: breaking down Product Requirements Documents (PRDs), creating task lists, and ensuring code style consistency across a team.
If you’re working on security-sensitive code generation, GPT-4 also takes the lead with 91.2% accuracy according to Windsurf benchmarks. It’s the safe middle ground. When you’re unsure which model to use, GPT-4 is rarely wrong, though it might not be the cheapest or the fastest. It’s the reliable senior engineer who won’t make flashy mistakes but might take longer than the junior intern to write boilerplate.
Gemini Flash: The Efficiency Engine
Gemini Flash is Google's cost-effective model optimized for speed and repetitive coding tasks. Released in September 2025, Gemini Flash 2.0 offers a 1 million token context window but focuses heavily on latency and cost. It scores lower on complex reasoning benchmarks (73.6% on HumanEval) but dominates in raw speed and price.
Gemini Flash is the king of repetitive tasks. Generating CRUD operations? It hits 92% accuracy, beating out both GPT-4 and Claude. Creating simple UI components? It boasts a 93.5% success rate. Why pay premium prices for work that is largely pattern-based? Gemini Flash processes these tasks at roughly 5 credits per task, compared to 18-20 credits for its heavier counterparts.
A key insight from case studies is Gemini’s "minimization" focus. While Claude might over-engineer a solution with five tables for a simple MVP, Gemini often suggests two. This isn’t always bad-it forces you to question complexity. Many developers report that using Gemini to review designs created by Opus helps catch over-engineering. It’s fast, cheap, and surprisingly competent for well-defined, isolated tasks.
Comparative Analysis: Which Model Wins Where?
To make this practical, let’s look at how these models stack up against each other in real-world scenarios. The table below summarizes key attributes based on recent industry benchmarks and pricing models.
| Attribute | Claude Opus 3.5 | GPT-4 Turbo | Gemini Flash 2.0 |
|---|---|---|---|
| Context Window | 1.2 Million Tokens | 128K Tokens | 1 Million Tokens |
| HumanEval Accuracy | 87.4% | 82.1% | 73.6% |
| Best For | Complex Architecture, DB Design | General Dev, Security Logic | CRUD, UI Components, Reviews |
| Relative Cost | High (~20 credits/task) | Medium (~18 credits/task) | Low (~5 credits/task) |
| Response Speed | Slower (Deep Reasoning) | Moderate | Fastest (47% faster on simple tasks) |
Notice the clear specialization. There is no winner in every category. Claude wins on depth, GPT-4 on balance, and Gemini on speed and cost. Your workflow needs all three.
Implementing a Tiered Workflow
So, how do you actually switch between these models without driving yourself crazy? Successful teams adopt a tiered workflow. Here is a proven structure:
- Tier 1: Critical Design (Max Models). Use Claude Opus or GPT-4 for database schemas, API contracts, and security audits. These outputs define the skeleton of your application. Errors here are expensive to fix later.
- Tier 2: General Development (Pro Models). Use GPT-4 Mini or Claude Sonnet for breaking down PRDs into tasks, writing unit tests, and refactoring existing code. These models offer a good balance of intelligence and speed.
- Tier 3: Repetitive Tasks (Free/Budget Models). Use Gemini Flash for generating boilerplate, simple UI components, and formatting data. Let it handle the grunt work.
One powerful technique is "multi-model verification." Generate a schema with Claude, then ask Gemini to review it for simplicity. Or write a function with GPT-4 and have Claude check it for edge cases. GitHub case studies show this reduces critical errors by 41%. It sounds like extra work, but catching a bug during design saves hours of debugging later.
Tools like Continue.dev help manage this. They allow you to swap models mid-conversation or set rules for automatic routing. Without such tools, context switching becomes a nightmare. A Stack Overflow survey found that 63% of developers struggle with the friction of moving between different AI interfaces. Automating the handoff is key.
Common Pitfalls and How to Avoid Them
Even with a good strategy, things go wrong. The biggest mistake is using a premium model for simple tasks. As one Reddit user put it, "Wasted 3 weeks and $800 having Opus write basic API endpoints before realizing Gemini Flash could do it 3x faster and 1/4 the cost." Don’t let perfectionism drain your budget.
Another issue is inconsistent code style. Different models have different "personalities." Claude tends to be verbose and explanatory; Gemini is concise; GPT-4 is neutral. If you mix them randomly, your codebase will look like it was written by three different people who hate each other. Define a strict style guide in your system prompts for each model to maintain uniformity.
Finally, beware of over-reliance on long-horizon tasks. Current models, including GPT-5.2 and Claude Sonnet 4.5, struggle with continuous work beyond two hours. They lose coherence. Break long tasks into smaller chunks. Verify outputs frequently. Don’t trust the AI to remember what it did 50 messages ago unless you’re using a model with a massive context window and explicitly managing memory.
The Future of Vibe Coding
The landscape is evolving fast. By 2027, analysts predict that "one model fits all" will be obsolete. We are already seeing specialized releases: Anthropic’s upcoming Opus 4.6 focuses on database optimization, while Google’s Gemini 2.1 aims for 2 million token contexts specifically for codebase analysis. OpenAI is improving multi-model coordination in GPT-5.3.
For developers, this means your role is shifting from coder to conductor. You spend less time typing syntax and more time selecting the right tool, verifying outputs, and orchestrating the flow. Experienced developers now spend 15-20% of their time just choosing and checking models. Embrace this change. Master model selection, and you’ll build faster, cheaper, and with higher quality than those still trying to brute-force everything with a single chatbot.
Is Claude Opus worth the extra cost for small projects?
Generally, no. For small projects with limited scope, the deep reasoning capabilities of Claude Opus are often overkill. Gemini Flash or GPT-4 Mini can handle the requirements at a fraction of the cost. Save Opus for projects where architectural complexity and long-term maintainability are critical.
Can I use multiple models in the same conversation?
Yes, but it depends on your interface. Tools like Cursor, Windsurf, and Continue.dev allow seamless switching between models within a project. However, standard web chats usually require starting a new thread for each model. Using integrated IDE extensions is highly recommended for a smooth multi-model workflow.
Which model is best for debugging?
It depends on the bug. For logical errors and complex state issues, Claude Opus is superior due to its chain-of-thought reasoning. For syntax errors or simple runtime exceptions, Gemini Flash is faster and sufficient. GPT-4 Turbo is a good all-rounder for general debugging assistance.
How does context window size affect vibe coding?
A larger context window allows the model to see more of your codebase at once, leading to more consistent and context-aware suggestions. Claude Opus and Gemini Flash have significantly larger windows than older GPT-4 versions, making them better suited for working with large, monolithic files or entire repositories.
Will AI replace developers in vibe coding workflows?
No, it changes the role. Developers become architects and reviewers. The AI handles implementation details, but humans must define requirements, select appropriate models, verify correctness, and ensure the final product aligns with business goals. The demand for skilled developers who understand model nuances is increasing.