You’ve built an LLM agent that looks brilliant in the demo. It plans tasks, calls tools, and delivers results. But put it into production, and you’ll hit a wall: the agent gets stuck in infinite loops, hallucinates success when it failed, or crashes because one API call timed out. The difference between a toy prototype and a reliable system isn’t just better prompting-it’s robust action verification and intelligent retry mechanisms.
Most developers treat retries as a simple "try again" command. That’s a mistake. In complex agentic workflows, a blind retry wastes tokens, increases latency, and often repeats the same error. You need a structured approach to verifying that an action actually worked before moving on, and a smart strategy for what to do when it doesn’t. This guide breaks down how to build execution loops that self-correct, using frameworks like VeriMAP and standard engineering best practices.
The Anatomy of a Reliable Execution Loop
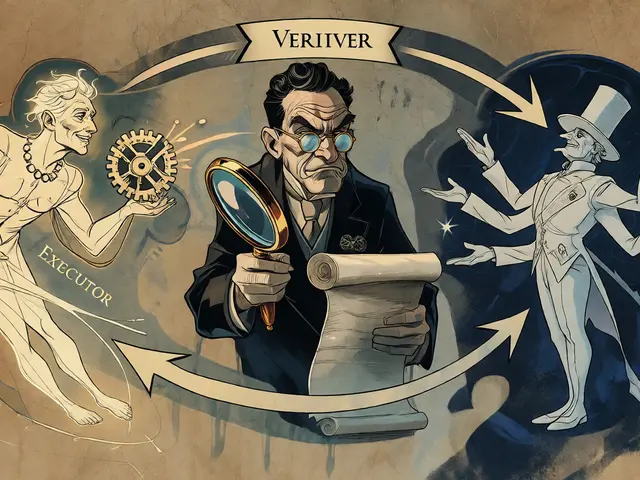
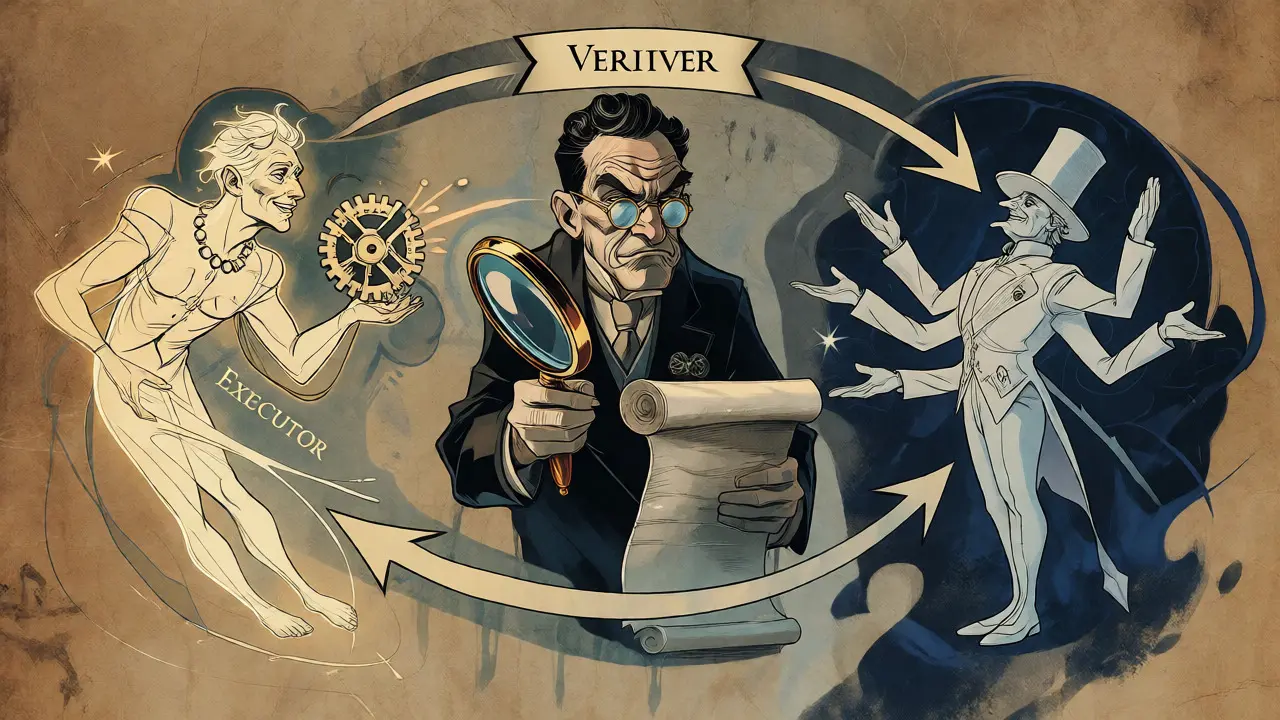
An agent’s core function is a loop: observe, think, act, observe again. Without checks, this loop is fragile. If the "act" step produces garbage, the next "observe" step feeds that garbage back into the model, compounding errors until the final output is nonsense. To fix this, we separate concerns into three distinct roles within the loop: the Executor, the Verifier, and the Coordinator.
The Executor is your standard agent component. It takes a subtask instruction, selects a tool (like a Python interpreter or a search API), and generates an output. The problem with Executors is they are optimistic. They assume their output is correct. The Verifier is the skeptic. It reviews the Executor’s output against specific criteria. The Coordinator manages the flow, deciding whether to accept the result, retry, or replan.
This separation prevents cascading failures. By isolating the verification logic, you can use different strategies for checking code versus checking factual accuracy. For instance, if the Executor writes a Python script, the Verifier shouldn’t just ask another LLM "is this good?" It should run the script. If the script throws an error, the Verifier knows exactly why, providing precise feedback for the next attempt.
Implementing Structured Verification Functions
How do you verify an action? You can’t rely on vibes. You need concrete Verification Functions (VFs). These come in two flavors: natural language-based and programmatic.
Natural language VFs use an LLM to evaluate the output. You prompt a verifier model with the original task and the executor’s result, asking it to check for completeness, accuracy, or adherence to constraints. This works well for subjective tasks, like summarizing a document or writing marketing copy. However, LLMs can be inconsistent. To mitigate this, use a strict logical AND strategy: if you have multiple checks (e.g., "is it under 100 words" AND "does it mention product X"), all must pass for the action to be considered successful.
Programmatic VFs are far more reliable for objective tasks. Instead of asking an LLM to judge code, you invoke a Python interpreter to run assertions. Did the file save? Does the JSON parse correctly? Is the returned ID valid? Programmatic checks provide deterministic truth. When a programmatic VF fails, it returns an error trace-a stack trace or exception message. This is gold for retries. Unlike a vague "this seems wrong," an error trace tells the Executor exactly which line failed and why, allowing for targeted corrections rather than blind guessing.
| Feature | Natural Language VF | Programmatic VF |
|---|---|---|
| Best For | Summaries, creative writing, sentiment analysis | Code execution, data formatting, API responses |
| Feedback Type | Textual explanation (can be vague) | Error traces, boolean flags (precise) |
| Cost/Latency | Higher (requires LLM call) | Lower (local execution) |
| Reliability | Moderate (prone to hallucination) | High (deterministic) |
Smart Retry Logic: Beyond Simple Repetition
When verification fails, don’t just hit "retry." A naive retry sends the exact same prompt to the model, which often yields the exact same error. Effective retry logic needs context. The Coordinator should update the context window with diagnostic signals from the previous failure before triggering the next attempt.
If a programmatic check failed with a `TypeError`, append that error to the prompt: "Previous attempt failed with TypeError: 'NoneType' object is not iterable. Please fix this." If a natural language check failed because the summary was too long, add: "Previous attempt was 150 words; target is 100 words." This context-aware approach transforms retries from random guesses into iterative refinements. Research shows that agents with access to failure history significantly outperform those without, as they learn from their immediate mistakes.
However, you must cap these attempts. Infinite retries kill budgets. Set a hard limit-typically 3 attempts per subtask. If the Executor fails three times in a row, stop trying to patch the current plan. Something is fundamentally wrong with the approach, not just the execution. This is where you shift from micro-retries to macro-replanning.
Handling Cascading Failures and Replanning
A single failed action can derail an entire workflow. Imagine an agent tasked with "Find the stock price, calculate growth, and email the report." If step 1 fails repeatedly, steps 2 and 3 never happen. After exhausting local retries, the Coordinator triggers a replanning phase. It collects the execution traces-including what failed and why-and asks the planner to generate a new sequence of actions.
This hierarchical recovery prevents deadlock. Instead of getting stuck on a broken tool, the agent might decide to try a different source for the stock price or skip the calculation if the data is unavailable. Limit the number of replanning cycles (e.g., max 5) to ensure termination. If the agent still can’t complete the task after five replans, it should return a clear failure report rather than looping forever.
Be wary of "Loop Drift," a phenomenon where agents fall into repetitive patterns despite having stop conditions. To combat this, implement global turn limits. Every agent run should have a maximum number of turns (LLM calls) and a total execution time cap (e.g., 5 minutes). Additionally, monitor for semantic repetition. Keep a sliding window of the last three actions. If the agent tries the same tool with similar arguments three times, force a break or trigger a replan. This watchdog timer pattern is brutal but necessary to prevent runaway costs.
Differentiating Error Types for Better Recovery
Not all errors are created equal. Treating a network timeout the same way you treat a validation error leads to inefficient retries. Production-grade systems categorize errors and apply specific strategies:
- Rate Limits (HTTP 429): Use exponential backoff with jitter. Wait 1 second, then 2, then 4, adding random noise to avoid synchronized retry storms from multiple agents.
- Validation Errors: Do not retry immediately. Rephrase the prompt or adjust parameters based on the error message. Blind repetition will fail again.
- Timeouts/Network Drops: These are transient. Safe to retry with backoff. Ensure operations are idempotent so repeated calls don’t corrupt state.
- Server Errors (5xx): Often indicate provider issues. Log them and consider falling back to a secondary model or tool if available.
Idempotency is critical here. Design your tools so that running the same action twice doesn’t create duplicate records or double-charge users. Use unique task IDs to detect duplicates. If an agent retries a "send email" action, the backend should recognize the ID and return the existing success status instead of sending a second email.
Practical Checklist for Robust Agents
Before deploying your agent, run through this checklist to ensure your verification and retry loops are solid:
- Define Clear Success Criteria: What does "done" look like for each subtask? Write explicit verification functions for every critical step.
- Separate Executor and Verifier: Don’t let the generator grade its own homework. Use a separate context or even a different model for verification.
- Cap Local Retries: Limit individual task retries to 3 attempts. Include failure diagnostics in the retry prompt.
- Implement Global Guards: Set max turns (e.g., 25) and max time (e.g., 300 seconds) to prevent infinite loops.
- Handle Rate Limits Gracefully: Implement exponential backoff with jitter for API calls.
- Enable Replanning: Allow the agent to change its plan if a step consistently fails, rather than forcing it to stick to a broken path.
- Log Everything: Store execution traces, verification results, and error types. You can’t improve what you can’t measure.
Building reliable LLM agents isn’t about making the model smarter; it’s about building a safety net around it. By combining structured verification, context-aware retries, and strategic replanning, you transform a flaky prototype into a dependable tool that handles the messy reality of real-world tasks.
What is the difference between a retry and a replan?
A retry attempts the same subtask again, usually with updated context or minor adjustments to the prompt. It assumes the overall plan is correct but the execution failed. A replan occurs when a subtask fails repeatedly or critically, indicating the current approach is flawed. The agent discards the remaining steps and generates a new high-level strategy to achieve the goal.
Why should I use programmatic verification over LLM-based verification?
Programmatic verification (e.g., running code or checking JSON structure) is deterministic, faster, and cheaper than calling an LLM to judge the output. It provides precise error messages (stack traces) that help the agent correct itself accurately. Use LLM-based verification only for subjective tasks where rules cannot be easily coded, such as tone or creativity.
How do I prevent my agent from entering an infinite loop?
Implement multiple safeguards: set a global maximum number of turns (e.g., 25), enforce a total execution time limit (e.g., 5 minutes), and detect repetitive actions by monitoring a sliding window of recent tool calls. If the same action repeats excessively, force a break or trigger a replan.
What is exponential backoff with jitter?
Exponential backoff is a retry strategy where the wait time between attempts doubles after each failure (1s, 2s, 4s, etc.). Jitter adds random variation to these wait times. This prevents multiple agents from retrying simultaneously at the exact same moment, which could overwhelm the server again (the "thundering herd" problem).
Can I use the same LLM for both execution and verification?
Yes, you can use the same base model, but they should operate in separate contexts. Ideally, use a smaller, faster model for verification to reduce cost and latency, or use the same model with a distinct system prompt focused solely on critical evaluation rather than generation. Separation ensures the verifier remains skeptical and doesn't inherit the executor's biases.