You know the feeling. You spend an hour explaining your preferences to a chatbot, only for it to forget them the moment you close the tab. It’s frustrating because the model is smart enough to understand you in the moment, but it has no concept of time. Standard Large Language Models (LLMs) are stateless by design. They don’t remember what happened five minutes ago unless that information is sitting right there in the current text prompt. This limitation breaks down quickly when you try to build agents that need to work on complex tasks over days or weeks.
To fix this, developers are moving beyond simple chat history. We’re building persistent agents with real memory systems. These aren't just logs; they are structured frameworks that allow an AI to retain, organize, and retrieve information across long periods. Think of it as giving the agent a brain that actually grows and changes based on experience. If you want your AI agents to be useful partners rather than one-off calculators, you need to master memory and state management. Here is how modern architectures handle this, from basic caching to sophisticated graph-based recall.
The Core Problem: Why Context Windows Aren't Enough
It’s tempting to think we can just make context windows bigger. After all, models like GPT-4o and Claude 3 Opus can handle massive amounts of text now. But throwing more tokens at the problem doesn’t solve the fundamental issue of relevance. If you stuff 100,000 words of past conversation into a prompt, the model gets confused. It struggles to identify which parts are critical and which are noise. This leads to "context rot," where performance degrades as the input grows longer.
Persistent memory solves this by decoupling storage from processing. Instead of keeping everything in the active prompt, the agent stores information externally. When it needs to act, it retrieves only the most relevant pieces. This mimics human cognition. You don’t recall every meal you’ve ever eaten when deciding what to have for dinner. You recall recent meals and dietary restrictions. Your agent needs to do the same thing. It needs a system that filters out the irrelevant so the LLM can focus on the task at hand.
Anatomy of Agent Memory Layers
Effective memory isn't a single bucket. It’s layered. Most robust agent architectures borrow from cognitive science, splitting memory into three distinct types. Understanding these layers helps you choose the right tools for each job.
- Working Memory: This is the immediate scratchpad. It holds the current goal, the last few steps taken, and the immediate observations. In technical terms, this often lives in the LLM's active context window or ephemeral RAM. It’s fast but volatile. If the session ends, working memory usually disappears unless explicitly saved.
- Short-Term Memory: This layer handles recent interactions that haven't yet been consolidated. It’s often implemented using cache layers like Redis. Short-term memory allows the agent to maintain continuity within a single session without hitting the latency costs of querying a database for every turn. It bridges the gap between the fleeting nature of working memory and the permanence of long-term storage.
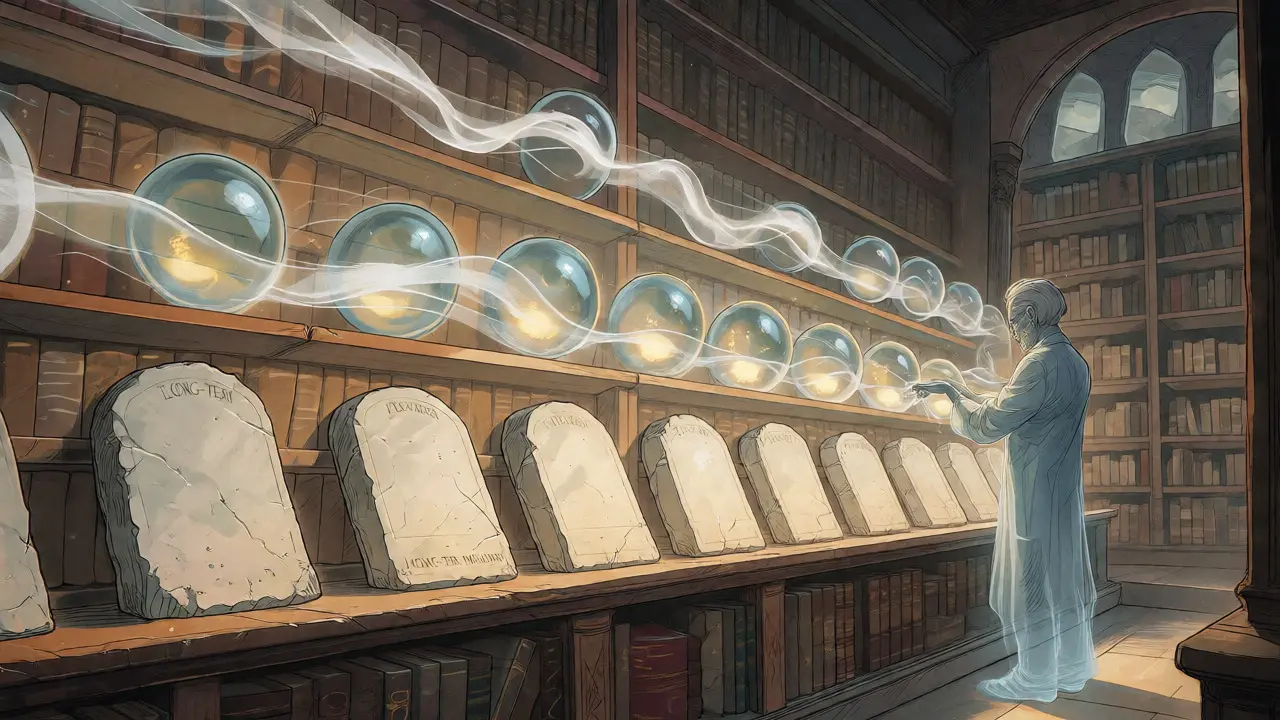
- Long-Term Memory: This is the permanent record. It stores facts, user preferences, and learned strategies indefinitely. This layer typically relies on Vector Databases such as Pinecone, Weaviate, or Chroma. Long-term memory is searchable via semantic similarity, allowing the agent to pull up specific details from months ago based on meaning, not just keywords.
Managing these layers requires different strategies. Working memory needs speed. Short-term memory needs low-latency access. Long-term memory needs durability and efficient indexing. Mixing them up causes bottlenecks. For instance, querying a vector database for every minor step in a reasoning chain slows the agent down significantly. Smart state management keeps high-frequency data in faster, temporary stores while archiving less frequent, high-value insights to the long-term store.
How Retrieval Actually Works
Storing data is easy. Getting it back out correctly is hard. The standard approach uses embeddings-numerical representations of text that capture semantic meaning. When a user asks a question, the agent converts that query into an embedding and searches its long-term memory for similar vectors. This is called semantic search.
However, pure semantic search has flaws. It might return a fact that is semantically similar but contextually wrong. To combat this, modern systems use hybrid retrieval. This combines vector search with keyword matching and metadata filtering. For example, if an agent is managing a calendar, it might filter results by date range before running the semantic search. This reduces noise and improves accuracy.
Another emerging technique is graph-based memory. Tools like Mem0 and Nemori represent memories as nodes in a graph, connected by relationships. Instead of just finding similar text, the agent traverses these connections. If you ask about a project, the agent doesn’t just find documents mentioning the project name; it follows links to team members, deadlines, and related tasks. This enables multi-hop reasoning, allowing the agent to answer complex questions that require connecting disparate pieces of information.
The Danger Zone: Error Propagation and Memory Bloat
Here is the dirty secret of agent memory: bad data sticks. If an agent hallucinates a fact and saves it to long-term memory, it will likely retrieve that error later. Worse, it might use that error to justify new actions, creating a feedback loop of nonsense. This is known as error propagation. Research published in May 2025 highlighted that naive memory addition strategies degrade performance over time. Simply saving every interaction leads to "memory bloat," where the database fills with redundant or low-quality records.
To prevent this, you need strict curation policies. Not everything should be remembered. Successful implementations use utility-based deletion. This means the agent periodically reviews its memory and deletes records that haven't been accessed recently or haven't contributed to successful outcomes. A study showed that effective deletion strategies could yield up to a 10% performance gain compared to keeping everything. It sounds counterintuitive to delete knowledge, but removing noise sharpens the signal.
| Strategy | Mechanism | Pros | Cons |
|---|---|---|---|
| Naive Addition | Save every interaction | Simple implementation | High noise, slow retrieval, error propagation |
| Summarization | Compress history into summaries | Reduces token count | Loses granular detail, risk of summarization errors |
| Utility-Based Deletion | Remove unused/low-value records | Keeps memory lean, high relevance | Requires tracking usage metrics |
| Graph-Based | Store entities and relationships | Supports complex reasoning | Complex setup, higher computational cost |
Frameworks and Tools for Implementation
You don’t have to build these systems from scratch. Several frameworks abstract the complexity of memory management. LangChain and AutoGen are popular choices for orchestrating agents. They provide built-in modules for connecting LLMs to various memory backends. LangChain, for instance, offers a variety of memory classes, from simple buffer memory to more advanced conversational memory that summarizes old chats.
For more specialized needs, consider dedicated memory engines. MemEngine decomposes memory into pluggable modules for encoding, retrieval, and forgetting. This modularity lets you swap components easily. Want to change your embedding model? Just plug in a new encoder. Want to add a reinforcement learning component for memory updates? Swap the update logic.
Another notable system is REMEMBERER. It implements episodic memory as a table of interaction records, storing task descriptions, observations, actions, and Q-values. By using reinforcement learning to update these values, the agent learns which experiences were helpful. This approach doesn't require fine-tuning the core LLM, making it cheaper and faster to iterate on.
Best Practices for State Consistency
State management is tricky in distributed systems. What happens if two agents are trying to update the same user profile simultaneously? Or if a process crashes mid-write? The Memory Consistency Protocol (MCP) addresses this by combining LLM-driven summarization with protocol enforcement. It ensures that even if the underlying data changes, the agent's understanding remains coherent.
When designing your own system, keep these rules in mind:
- Be Selective: Only save information that has proven utility. Use evaluators to score the importance of new memories before adding them.
- Use Metadata: Tag memories with timestamps, source IDs, and confidence scores. This allows for filtered retrieval later.
- Monitor Latency: Retrieval adds overhead. Benchmark your system to ensure memory lookups don’t slow down response times unacceptably.
- Test for Drift: Run periodic checks to see if the agent’s behavior aligns with its stored memories. Look for signs of hallucination or contradiction.
The field is moving fast. As of 2026, we are seeing a shift from theoretical papers to practical deployment. Frameworks are maturing, and benchmarks like MemBench help developers compare different approaches on factual accuracy and efficiency. There is no one-size-fits-all solution yet. A customer support bot needs different memory structures than a coding assistant. Start simple, measure the impact, and add complexity only when necessary.
What is the difference between short-term and long-term memory in LLM agents?
Short-term memory typically refers to recent conversation history kept in fast-access caches like Redis or within the active context window. It handles immediate continuity. Long-term memory is persistent storage, often in vector databases, used to retain facts, preferences, and learned strategies across sessions and over long periods.
Why does memory bloat degrade agent performance?
Memory bloat occurs when an agent saves too much irrelevant or low-quality information. This increases retrieval noise, causing the agent to fetch incorrect or outdated contexts. It also slows down retrieval speeds and can lead to error propagation, where past mistakes influence future decisions negatively.
Do larger context windows eliminate the need for external memory?
No. While larger context windows allow more information to be processed at once, they do not solve issues of relevance or persistence. Stuffing large histories into the prompt can confuse the model and increase costs. External memory allows for selective retrieval of only the most relevant information, improving both accuracy and efficiency.
What is a vector database and why is it used for agent memory?
A vector database stores data as numerical embeddings that represent semantic meaning. It is used for agent memory because it allows for fast semantic search. The agent can find memories that are conceptually similar to a query, even if they don't share exact keywords, enabling more natural and flexible recall.
How do graph-based memory systems differ from vector stores?
Vector stores rely on similarity scores between embeddings. Graph-based systems, like those used in Mem0 or Nemori, store entities and their relationships as nodes and edges. This allows agents to perform multi-hop reasoning, tracing connections between concepts rather than just finding similar text snippets.