You’re staring at a training run that’s taking forever. Or maybe your inference latency is too high for production. You know you need to tweak the Transformer architecture, but do you add more layers (depth) or make them bigger (width)? It’s not just about throwing more parameters at the wall. Recent research from late 2025 and early 2026 shows that this choice drastically changes how fast your model runs and what it can actually learn.
Here’s the quick truth before we get into the weeds:
- Width wins on speed: Wider, shallower models train and infer significantly faster because GPUs love parallelism.
- Depth wins on logic: For complex language tasks requiring compositional understanding, deeper models often generalize better.
- It depends on the task: Graph algorithms prefer wide/shallow; natural language often prefers deep/narrow.
- Hardware matters: Your GPU cluster dictates what’s practical. Don’t fight the hardware.
The Core Tradeoff: Layers vs. Dimensions
Let’s clear up the jargon. When we talk about Transformer depth, we mean the number of stacked encoder-decoder blocks. Each layer adds a step in processing information. Transformer width refers to the embedding dimension and the size of the hidden layers within each block. A wider model has more neurons per layer, allowing it to hold more information simultaneously.
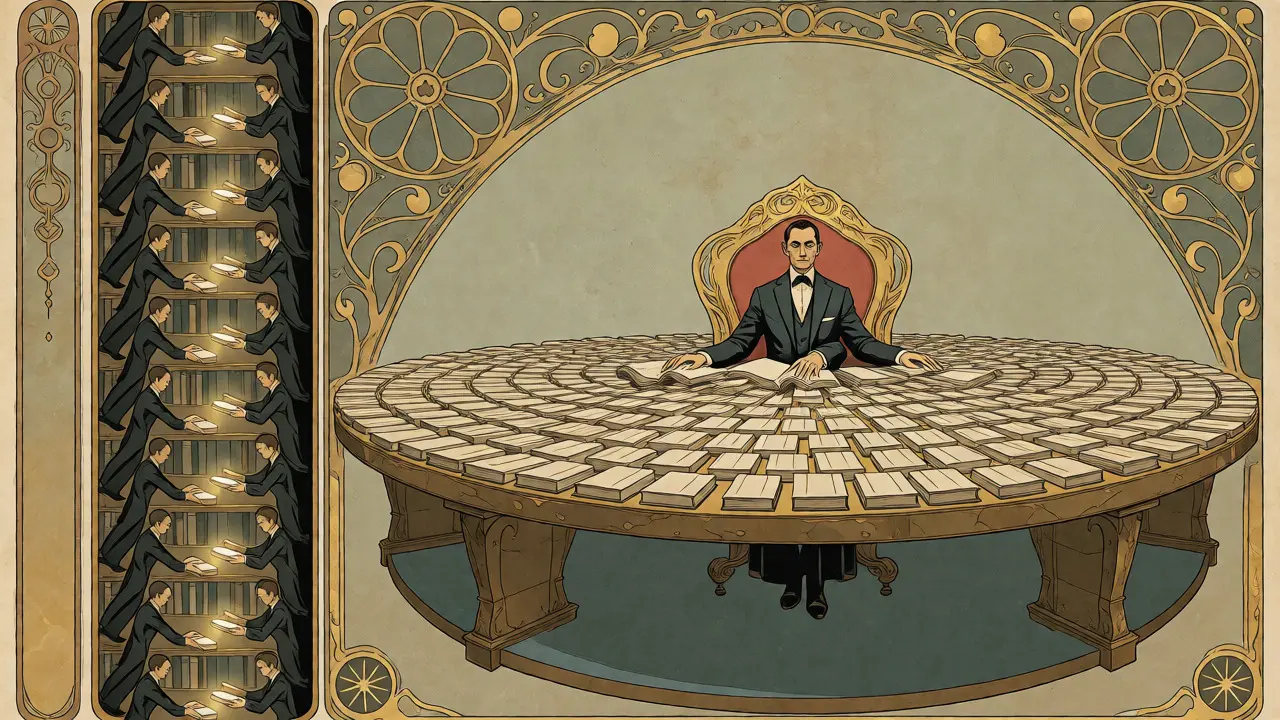
Imagine you’re organizing a library. Depth is like having ten librarians standing in a line, each passing the book to the next. They can do very complex sorting steps sequentially. Width is like having one librarian with a massive desk who can look at many books at once. The first approach (depth) allows for intricate, step-by-step reasoning. The second (width) allows for rapid, parallel scanning.
For years, the default assumption was "more layers = smarter." But as we scale to billions of parameters, that assumption breaks down. We are now seeing a shift where researchers are questioning if we’ve been building skyscrapers when we should have been building sprawling campuses.
Why Width Is Faster (And Why That Matters)
If you’ve ever tried to optimize inference time, you know that GPU parallelization is king. Modern graphics cards are designed to perform thousands of calculations simultaneously across a single matrix operation. This is where width shines. When you increase the width of a transformer layer, you are essentially giving the GPU more data to chew on in parallel.
In contrast, depth introduces sequential dependencies. Layer 2 cannot start until Layer 1 finishes. This creates a bottleneck known as the "critical path" in computation. Even if each layer is small, stacking fifty of them means waiting fifty times longer than stacking five wide ones.
| Metric | Deep & Narrow Architecture | Shallow & Wide Architecture |
|---|---|---|
| Inference Latency | Higher (Sequential bottlenecks) | Lower (High parallelism) |
| Training Speed | Slower (More memory transfers between layers) | Faster (Better GPU utilization) |
| Memory Usage | Lower peak memory per step | Higher peak memory (larger matrices) |
| Generalization (Language) | Better for complex reasoning | Comparable or slightly lower |
| Generalization (Algorithms) | Requires significant depth | Sufficient with linear width |
A recent empirical study highlighted that shallow-and-wide transformers reduce total training and inference time significantly compared to their deep counterparts, even when the final accuracy remains similar. If you are deploying a chatbot where response time is critical, going wide is often the pragmatic choice.
When Depth Actually Wins: The Case for Reasoning
So, why haven’t we all switched to wide models? Because some problems require sequential thinking. In natural language processing, specifically for tasks involving compositional generalization, depth provides an advantage. Compositional generalization is the ability to understand new combinations of known concepts. Think of it like learning grammar rules. To parse a complex sentence structure, the model needs to apply multiple transformations in order.
Studies testing models at scales like 41 million, 134 million, and 374 million parameters found that deeper models handled out-of-distribution examples better. These are tricky cases the model hasn’t seen during training. A deep model can break down a complex query into smaller logical steps, whereas a wide model might try to match patterns holistically and fail when the pattern shifts slightly.
This suggests that if your application involves heavy reasoning-like code generation, mathematical problem solving, or legal document analysis-you shouldn’t sacrifice depth entirely. You need those sequential layers to build up abstract representations.
Algorithmic Tasks: A Different Ballgame
Things get interesting when we move away from pure language to algorithmic tasks, particularly graph-based problems. Research presented at NeurIPS 2025 revealed something counterintuitive: for many graph problems, constant depth is sufficient if you increase the width linearly with the input size.
Prior work suggested that narrow models needed logarithmic depth to solve these tasks. But by making the model wider, you can keep the depth fixed. This is huge for scalability. It means you don’t need to add more layers as your data gets larger; you just need bigger matrices. However, there’s a catch. For certain hard graph connectivity problems, quadratic width is required to maintain constant depth. This establishes a theoretical limit: shallow-and-wide architectures belong to a complexity class called TC^0, which means they struggle with problems requiring iterative refinement unless they are incredibly wide.
Practical Guidelines for Architects
How do you decide? It comes down to three questions:
- What is the primary bottleneck? If it’s latency or cost-per-inference, go wider. If it’s accuracy on complex, unseen examples, go deeper.
- What is the nature of the task? Is it pattern matching (wide) or sequential reasoning (deep)? Code generation sits somewhere in the middle, often benefiting from a balanced approach.
- What hardware do you have? If you have access to high-bandwidth memory (HBM) and powerful GPUs like the H100s, you can afford the memory hit of wider models. If you are running on edge devices with limited RAM, depth might be cheaper in terms of parameter storage, though slower in execution.
Don’t fall into the trap of assuming one rule fits all. The landscape of transformer implementations is complex. There is no universal "best" shape. Instead, think of depth and width as two dials you tune based on the specific constraints of your project.
The Future: Hybrid Approaches
We are moving toward hybrid architectures. Instead of choosing one extreme, newer designs use variable width across layers. Early layers might be wider to capture broad features, while later layers become narrower and deeper to refine logic. Other approaches dynamically adjust depth based on input complexity, skipping layers for simple queries and using all of them for complex ones.
The key takeaway for 2026 is that architectural choices are no longer just about capacity. They are about efficiency and alignment with the task’s computational nature. Stop copying the config file from GPT-4 blindly. Look at your data, measure your latency, and choose the shape that fits your problem.
Does increasing width always improve performance?
No. While width improves parallelism and can help with certain tasks, it increases memory consumption and computational cost per layer. Beyond a certain point, adding width yields diminishing returns compared to adding depth, especially for tasks requiring sequential reasoning.
Which is better for inference speed, depth or width?
Width is generally better for inference speed on modern GPUs. Wider layers allow for greater parallelization, reducing the sequential dependency chain that slows down deep models. Shallow-and-wide models typically have lower latency than deep-and-narrow models with similar parameter counts.
Can shallow models handle complex language tasks?
They can, but they may struggle with compositional generalization. Deep models are better at breaking down complex sentences and applying multi-step logic. Shallow models rely more on pattern matching, which can fail on novel or highly structured linguistic inputs.
How does batch size affect the depth-width tradeoff?
Larger batch sizes benefit wider models because GPUs can process more data in parallel within each layer. Deeper models suffer more from increased batch sizes due to the cumulative sequential overhead across many layers, potentially leading to higher memory usage and slower throughput.
Is there a standard ratio for depth to width?
There is no single standard, but common heuristics suggest keeping the embedding dimension (width) roughly equal to or slightly larger than the number of layers (depth) for balanced models. However, this varies widely by application; vision transformers often favor width, while some reasoning-focused NLP models favor depth.