You’ve built a Large Language Model. It passes the benchmarks. It looks great in the demo. But then it hits production, and suddenly your customer support bot starts hallucinating return policies or your legal summarizer misses a critical liability clause. The gap between "benchmark success" and "real-world reliability" is where most AI projects die. Purely automated metrics like BLEU or ROUGE don’t care if your tone is wrong or if you just insulted a VIP client. Purely manual review doesn’t scale when you’re processing millions of interactions a day.
This is where Human-in-the-Loop (HITL) Evaluation Pipelines become non-negotiable. Think of HITL not as a safety net, but as an engine. It’s a hybrid architecture that uses the speed of LLM-as-a-Judge for bulk screening while reserving human expertise for the nuanced, high-stakes edge cases that algorithms consistently miss. If you are deploying generative AI in 2026, you aren’t just shipping a model; you are shipping a feedback loop. Here is how to build one that actually works.
The Death of Pure Automation
Let’s be real: relying solely on automated evaluation is a gamble. LLMs are incredible at pattern matching, but they struggle with ambiguity, context-heavy nuance, and subjective quality judgments. When you use an LLM to evaluate another LLM-a technique known as LLM-as-a-Judge-you get scalability. You can score thousands of outputs in minutes. But these judges have biases. They might prefer verbose answers over concise ones, or they might fail to detect subtle factual errors in specialized domains like healthcare or finance.
Conversely, traditional human evaluation is accurate but painfully slow and expensive. A team of annotators can only handle so many tickets before fatigue sets in, leading to inconsistent labeling. The solution isn’t to choose one over the other. It’s to orchestrate them. HITL pipelines recognize that humans should be the ultimate arbiters of quality, especially in high-stakes settings, while automated systems handle the routine heavy lifting. This approach addresses the two biggest killers of AI adoption: cost and trust.
Anatomy of a Tiered Evaluation Architecture
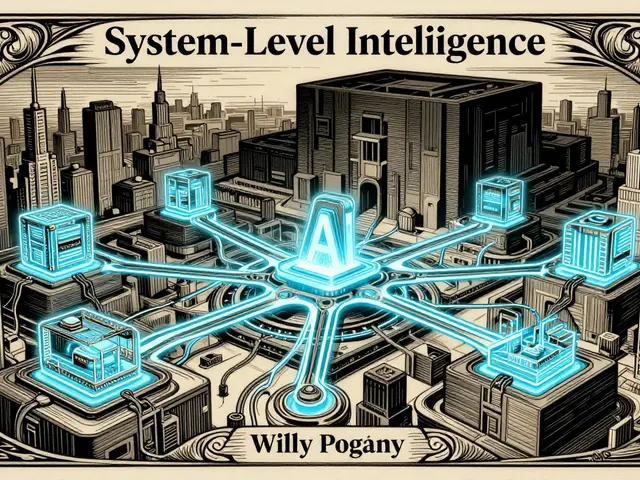
A robust HITL pipeline isn’t just a button that sends data to humans. It’s a tiered system designed to filter noise before it reaches your expensive expert reviewers. Most successful implementations follow a three-tier structure.
Tier 1: Automated Screening. This is your first line of defense. An LLM judge evaluates every single output against predefined criteria. Is the answer safe? Does it follow the format? Is it relevant? This tier handles 80-90% of cases automatically. It filters out clear failures (like empty responses or obvious hallucinations) and flags everything else for further review. By using binary questions here-such as "Does this response contain PII?"-you get fast, reliable filtering.
Tier 2: Human Review & Calibration. This is where the magic happens. Human experts don’t look at everything. They look at what the machine flagged. This includes low-confidence scores from the LLM judge, random samples for quality assurance, and specific edge cases defined by business rules. These human labels serve as "ground truth." They are used to calibrate the automated judges, ensuring the AI learns what "good" actually looks like in your specific context.
Tier 3: Continuous Feedback Loops. Data from Tier 2 flows back into the system. If humans consistently disagree with the LLM judge on a certain type of query, the prompt template for the judge is updated. If humans find a recurring error in the model, those examples are added to the fine-tuning dataset. This creates a self-improving cycle where both the evaluator and the evaluated model get smarter over time.
Smart Routing: Uncertainty and Diversity Sampling
One of the biggest mistakes teams make is sending random data to human reviewers. That’s inefficient. Instead, you need smart routing strategies that maximize the value of human attention.
- Uncertainty Sampling: Route outputs where the LLM judge shows low confidence. If an automated scorer gives a 50/50 split between "pass" and "fail," send it to a human. Focus human expertise on genuinely ambiguous cases rather than obvious successes or failures.
- Diversity Sampling: Ensure your human reviewers see a variety of input types. If you only look at common queries, you’ll never catch rare but catastrophic failures. Use clustering techniques to ensure human review covers diverse topics, lengths, and user intents.
- Disagreement Resolution: If you use multiple LLM judges and they disagree, escalate that case to a human. Consensus among machines is a signal; disagreement is a red flag worth investigating.
Active learning integration plays a huge role here. By training prediction models with minimum cost, you let humans provide training data specifically where the computer struggles. This isn’t just about fixing bugs; it’s about teaching the model the implicit rules of your domain that no amount of pre-training captured.
Bias Mitigation and Domain Specificity
AI models learn from data, and data contains bias. Without human oversight, your model will happily replicate historical prejudices found in its training set. HITL pipelines act as a safeguard. During the evaluation phase, human reviewers can identify outputs that are technically correct but socially inappropriate or biased. For example, a medical chatbot might give accurate advice but use a tone that feels dismissive to elderly patients. An automated metric won’t catch that tone issue. A human reviewer will.
This is particularly critical in specialized domains. General-purpose LLMs are great at chatting about movies, but they often lack the precision required for legal contracts or medical diagnoses. In these fields, the complexity and nuance of language necessitate human experts working in conjunction with automated systems. By adopting a HITL approach, you leverage the depth and discernment of human evaluators to maintain accuracy, fairness, and relevance.
| Feature | Pure LLM-as-a-Judge | Pure Manual Review | HITL Pipeline |
|---|---|---|---|
| Scalability | High (Millions/day) | Low (Hundreds/day) | High (Hybrid scaling) |
| Cost | Low (Compute only) | Very High (Labor intensive) | Moderate (Optimized labor) |
| Nuance Handling | Weak (Struggles with edge cases) | Strong (Context aware) | Strong (Targeted expertise) |
| Consistency | High (Deterministic prompts) | Variable (Human fatigue/bias) | High (Calibrated by humans) |
| Adaptability | Static until re-prompted | Slow to update guidelines | Continuous improvement loop |
Implementation Pitfalls to Avoid
Building a HITL pipeline sounds straightforward, but execution is tricky. First, avoid vague rubrics. If you tell your LLM judge to "check for quality," it will guess. You need specific, measurable criteria embedded in the prompt templates. Define exactly what a score of 1 vs. 5 means for clarity, factuality, and tone.
Second, don’t ignore versioning. Your model changes. Your prompts change. Your human guidelines change. If you don’t track which version of the evaluator scored which batch of data, you can’t correlate improvements in model performance with changes in evaluation logic. Analytics tools must track how human input shifts model behavior over time.
Finally, beware of reviewer fatigue. Even with smart routing, humans get tired. Rotate tasks, provide clear examples of good vs. bad reviews, and ensure your interface is intuitive. If the tooling is clunky, your data quality drops. Real-time interfaces allow product and QA teams to flag failure cases as they appear in production, keeping the feedback loop tight.
Key Takeaways
- Hybrid is Best: Neither pure automation nor pure manual review scales effectively alone. Combine them.
- Filter Before You Pay: Use LLMs to screen 80-90% of traffic, saving human effort for complex cases.
- Route Smartly: Use uncertainty sampling to send only ambiguous cases to humans.
- Close the Loop: Human corrections must feed back into model fine-tuning and evaluator calibration.
- Define Success Clearly: Vague evaluation criteria lead to noisy data and poor model alignment.
What is the main benefit of Human-in-the-Loop evaluation?
The primary benefit is balancing scalability with accuracy. It allows organizations to process large volumes of AI interactions quickly using automated tools while ensuring that nuanced, high-stakes, or ambiguous outputs receive expert human scrutiny, thereby maintaining high standards of quality and safety.
How does LLM-as-a-Judge work in these pipelines?
LLM-as-a-Judge involves using a separate, powerful language model to evaluate the outputs of your primary model based on predefined criteria. It acts as an initial screener, assigning scores or labels to outputs. Its results help filter data, identifying clear passes/fails and flagging uncertain cases for human review.
Why is uncertainty sampling important?
Uncertainty sampling ensures that human reviewers focus their limited time on cases where the automated system is least confident. By routing outputs with low confidence scores to humans, you maximize the impact of human feedback, correcting the model where it is most likely to be wrong.
Can HITL pipelines help reduce AI bias?
Yes. Human reviewers can detect subtle biases in tone, representation, or factual interpretation that automated metrics might miss. By flagging these issues and feeding corrected examples back into the training process, HITL pipelines actively mitigate bias embedded in data and algorithms.
What is model drift and how does HITL address it?
Model drift occurs when a model's performance degrades over time due to changes in user behavior or data distribution. HITL pipelines continuously monitor new inputs. If humans notice a trend of declining quality or new types of errors, they can trigger retraining or prompt adjustments, keeping the model aligned with current realities.
Bonnie Watt
September 15, 2026 AT 13:50Everyone is hyping this up like it's some revolutionary new tech, but let's be real for a second: this is just expensive babysitting for models that can't handle basic nuance without someone holding their hand.
You talk about "scalability" and "efficiency," but the moment you introduce human reviewers into the loop, your costs skyrocket and your timelines stretch out indefinitely. I've seen too many teams fall into the trap of thinking they need a human to check every single edge case, only to realize they've built a bottleneck that kills their product velocity. The LLM-as-a-Judge concept is already flawed because judges have inherent biases, so adding humans on top just creates a messier feedback loop where nobody knows who is actually right. It feels less like an engineering solution and more like a crutch for lazy prompt engineering.
Kim Edwards
September 17, 2026 AT 08:34OH MY GOD, FINALLY SOMEONE SAID IT!
I am literally shaking right now reading this because it validates EVERYTHING I have been screaming into the void for the past two years! People think AI is magic, but when it hallucinates a return policy that doesn't exist, it’s not a bug, it’s a catastrophe waiting to happen! This post is the holy grail of truth! We are shipping broken products and calling them innovative! The pain! The sheer agony of watching companies ignore the human element until their reputation burns to the ground! It’s tragic! It’s beautiful! It’s exactly what we needed to hear!
Elisabeth Ballet
September 19, 2026 AT 02:32Hey Bonnie, I totally get where you're coming from with the cost concerns, but I think you might be looking at this through a lens that assumes all HITL implementations are created equal.
The key here isn't throwing bodies at the problem indiscriminately; it's about smart routing and tiered architecture. If you implement uncertainty sampling correctly, you aren't paying humans to review obvious successes or obvious failures. You are paying them to solve the hardest problems that automation simply cannot crack yet. That ROI is massive when you consider the cost of a bad customer interaction in high-stakes domains like legal or healthcare. Don't let the fear of labor costs stop you from building a system that actually earns trust. You’ve got this if you focus on the calibration loop rather than just the initial labeling effort.
Joanna Mucha
September 19, 2026 AT 05:47One must pause and consider the ontological weight of "truth" in these pipelines.
We are attempting to quantify the ineffable nuances of human language using binary logic gates and probabilistic matrices. The article suggests that humans are the "ultimate arbiters," but are they? Or are they merely another layer of bias, filtered through fatigue and subjective interpretation? The idea that we can "calibrate" an AI to match human judgment presumes that human judgment is consistent, which any student of psychology knows is a fallacy. We are building mirrors that reflect our own inconsistencies back at us, dressed up in the sleek clothing of technological progress. It is a fascinating, albeit slightly terrifying, dance between the organic mind and the synthetic judge.
Brenna Gonedrman
September 20, 2026 AT 15:30Actually, that is completely wrong.
Human judgment is NOT inconsistent if you use proper rubrics. Period. The article clearly states that vague rubrics cause noise, which means the problem is implementation, not the concept itself. You are confusing bad execution with bad theory. Everyone knows that specific, measurable criteria eliminate subjectivity. If your reviewers are disagreeing, your guidelines are trash, not your humans. Simple fact.
Courtney Wagstaff
September 20, 2026 AT 22:14Hey y'all, just wanted to drop in and say this is super cool stuff 🌟
I love the idea of treating the evaluation pipeline like an engine instead of just a safety net. It makes the whole process feel way more dynamic and alive. The part about diversity sampling really resonated with me-it’s like making sure your AI gets a well-rounded education instead of just studying the same textbook over and over. Definitely going to try clustering techniques on my next project to keep things fresh and spicy! ✨
tiffany King
September 21, 2026 AT 00:41This is such a great reminder that technology should serve people, not replace the critical eye.
It’s easy to get lost in the metrics and forget that behind every interaction is a human being expecting empathy and accuracy. Building these loops isn't just about fixing errors; it's about respecting the user experience enough to ensure quality. Keep pushing forward, everyone-this hybrid approach is definitely the future we want to build together!