Imagine spending months building a brilliant customer service chatbot, only to get hit with a fine that wipes out your quarterly profits because the data traveled across a border it wasn't supposed to cross. That is the reality for many companies deploying Large Language Models (LLMs) today. The rules of the game changed dramatically in 2026, especially with the EU AI Act taking full effect on August 15, 2026. Data residency-the physical location where your data lives-is no longer just a legal preference; it is a technical requirement that dictates how you build your AI infrastructure.
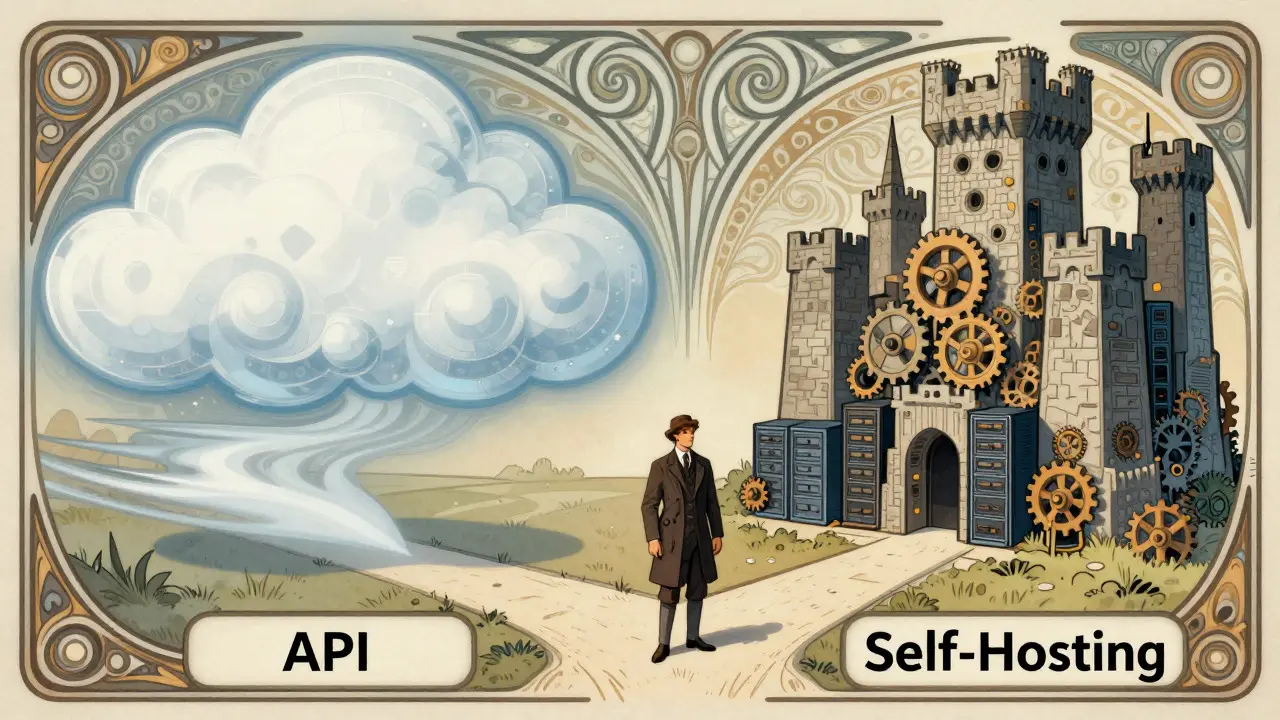
You have two main paths for deploying these powerful models: using a managed API from big tech providers or hosting open-source models yourself. Each choice comes with different trade-offs regarding control, cost, and compliance. If you are trying to figure out which route keeps you safe from regulators while keeping your app fast and affordable, you need to look at the specific requirements of your target markets.
The New Reality of Data Residency
Data residency asks a simple question: "In which country does my data live?" It is different from data sovereignty, which covers the broader laws a country asserts over data within its borders. In 2026, the line between them has blurred. Regulations now care not just about where the database sits, but where the processing happens. When an LLM processes a prompt, it generates logs, metadata, and sometimes temporary embeddings. Regulators like those in the European Union and China view this processing as part of the data lifecycle.
The stakes are high. Under the General Data Protection Regulation (GDPR), fines can reach 4% of global annual revenue. Australia’s recent reforms allow penalties up to 28% of turnover for serious breaches. These aren't abstract threats. In early 2026, several fintech startups faced shutdowns after auditors discovered their AI training data was being routed through servers in jurisdictions without adequate protection agreements. The lesson is clear: if you don't know exactly where your data goes during inference and training, you are already non-compliant.
API-First Approach: Speed vs. Control
Using a proprietary API, such as those offered by major cloud providers, is the fastest way to get started. You send a request, you get a response, and you move on. For years, this was the default choice for developers who wanted to avoid the headache of managing GPUs and scaling infrastructure. However, in the current regulatory climate, this convenience comes with significant risks.
When you use a public API, you often lose visibility into where the data is processed. While providers offer regional endpoints, the internal routing of requests can still span multiple data centers for redundancy or load balancing. Unless you have a dedicated enterprise agreement with strict data localization clauses, your user's prompt might briefly touch a server in a non-approved region before returning the answer. This "brief touch" is enough to trigger violations under strict laws like China's Personal Information Protection Law (PIPL).
Furthermore, many API providers retain usage data for model improvement. Even if the raw text is anonymized, derived analytics and metadata can sometimes be linked back to individuals. Professor Kenji Tanaka from the Tokyo Institute of Technology warned in early 2026 that metadata alone can carry enough identifying information to breach localization requirements. If your business operates in the EU or APAC, relying solely on a standard API without rigorous contractual guarantees is a gamble.
Open Source and Self-Hosting: The Compliance Shield
This is where open-source models shine. By hosting models like Llama 3 or Mistral on your own infrastructure, you gain complete control over the data pipeline. You decide which server racks process the requests. You decide which encryption keys decrypt the data. You decide if the data ever leaves the building-or even the city.
Self-hosting allows for true data localization. If your customers are in Germany, you deploy the model in a Frankfurt data center. If they are in Dubai, you use a local UAE server. There is no hidden routing. No third-party logging unless you configure it. This level of transparency is exactly what regulators are demanding. According to a 2026 study by Signzy, strictly localized deployments reduced compliance risk by 92%, even though they incurred 15-22% higher latency compared to centralized global models.
However, self-hosting is not free. It requires expertise. You need engineers who understand GPU optimization, container orchestration, and jurisdiction-aware networking. The average time to deploy a compliant, self-hosted LLM environment is now 4.7 months, according to industry surveys. You also bear the cost of hardware and electricity. But for regulated industries like healthcare, finance, and government services, this cost is often lower than the potential penalty of a single breach.
Regional Regulatory Landscapes
Not all countries treat data the same way. Your deployment strategy must adapt to the specific rules of each market you serve. Here is how the major regions stand in mid-2026:
| Region | Key Regulation | Requirement Level | Impact on LLM Choice |
|---|---|---|---|
| European Union | GDPR + AI Act | High (Adequacy-based) | Requires transparent data flows; API acceptable if provider offers EU-only processing with DPAs. |
| China | PIPL | Very High (Absolute Localization) | Personal data must stay in China. Self-hosting or local joint ventures are mandatory. |
| Australia | Privacy Act 1988 | High (Sector-specific) | Government and critical infrastructure data must remain in-country. Hybrid models preferred. |
| UAE | Federal Decree-Law | High (Financial/Gov) | Financial records must be on local servers. Other sectors can use approved destinations. |
| Brazil | LGPD | Medium-High | Transfers allowed to adequate nations or via contract. Regional APIs viable with safeguards. |
In the EU, the new AI Act introduces risk-based categories. High-risk systems, such as biometric surveillance or credit scoring, require thorough documentation and human oversight. Using an API here is possible, but you must ensure the provider provides detailed audit logs and guarantees that no training occurs on your production data without consent. In China, the rules are stricter. Cross-border transfers require security assessments, making self-hosted open-source models the only practical option for most foreign companies wanting to serve Chinese citizens directly.
Hybrid Architectures: The Best of Both Worlds?
Many enterprises are moving toward hybrid architectures. Instead of choosing one path globally, they segment their workloads. Low-sensitivity tasks, like general content summarization or code generation for internal tools, might use a flexible API to save costs. High-sensitivity tasks, involving personal identifiable information (PII) or financial records, are routed to self-hosted open-source models in local data centers.
This approach requires sophisticated routing logic. You need an intelligent gateway that inspects incoming requests, classifies their sensitivity, and directs them to the appropriate backend. TrueFoundry and similar platforms have emerged to help manage this complexity, offering jurisdiction-aware routing that ensures prompts never leave the designated region. However, this adds architectural overhead. You are now managing two types of infrastructure, two sets of monitoring tools, and two compliance frameworks.
Disaster recovery (DR) is another trap in hybrid setups. A common mistake is setting up automatic failover to a cheaper, out-of-region data center. If your primary site in Singapore goes down, and traffic fails over to Sydney, you might violate Australian or Singaporean localization laws. In 2026, 78% of enterprises had to redesign their DR plans because they inadvertently violated residency rules during testing. Always configure DR within the same jurisdiction, even if it means paying more for redundant local capacity.
Cost and Performance Trade-offs
Let's talk numbers. Self-hosting open-source models is generally more expensive upfront. You need to buy or lease GPUs, pay for power and cooling, and hire specialized staff. Operational costs can be 30-45% higher than using a managed API, according to Signzy's 2026 survey. However, at scale, the marginal cost per token for self-hosted models drops significantly. If you have millions of users, self-hosting can eventually become cheaper than API fees.
Performance is another factor. Centralized APIs benefit from massive economies of scale and optimized hardware, often resulting in lower latency. Localized deployments may suffer from higher latency due to less optimized local infrastructure or smaller cluster sizes. But for most conversational AI applications, a 100-200ms increase in latency is imperceptible to the user. The trade-off is usually worth it for the peace of mind regarding compliance.
Implementation Checklist for 2026
If you are planning an LLM deployment this year, follow these steps to ensure you meet data residency requirements:
- Classify your data: Identify which inputs contain PII, financial data, or health records. Not all data needs the highest level of protection.
- Map your jurisdictions: List every country where your users reside and research their specific data localization laws.
- Evaluate API contracts: If using an API, demand explicit clauses guaranteeing data stays in specific regions. Check for sub-processing rights.
- Consider open-source alternatives: For sensitive data, evaluate models like Llama 3 or Mistral for self-hosting.
- Design jurisdiction-aware routing: Build a gateway that routes requests based on user location and data sensitivity.
- Secure your keys: Use customer-managed encryption keys (CMEK) so that decryption only happens in your controlled environment.
- Test disaster recovery locally: Ensure failover mechanisms do not route data across borders.
Looking Ahead
The trend is clear: fragmentation. While some regions like ASEAN are exploring mutual recognition frameworks, major economic blocs are diverging. By 2027, Gartner predicts that 45% of global enterprises will maintain at least three separate LLM deployment environments to comply with regional rules. This means flexibility is key. Locking yourself into a single vendor or architecture might seem easy now, but it could become a liability later.
Whether you choose API or open-source depends on your risk tolerance and budget. For startups in unregulated sectors, APIs remain a viable shortcut. For established businesses in finance, healthcare, or government, self-hosted open-source models are becoming the standard for trust and compliance. The technology is ready; the challenge is navigating the complex web of global laws.
What is the difference between data residency and data sovereignty?
Data residency refers to the physical location where data is stored and processed. Data sovereignty is the concept that data is subject to the laws and governance structures of the nation in which it is physically located. In practice, residency is the technical implementation required to satisfy sovereignty laws.
Can I use a public API for GDPR-compliant AI applications?
Yes, but with conditions. You must ensure the API provider offers EU-specific endpoints and signs a Data Processing Agreement (DPA) that guarantees data does not leave the EU. You should also verify that the provider does not use your input data for model training without explicit consent.
Why are open-source models better for data residency?
Open-source models can be hosted on your own infrastructure, giving you complete control over where the data is processed. Unlike closed APIs, there is no black box. You can ensure that prompts, responses, and logs never leave your designated geographic boundaries, satisfying strict localization laws.
How does the EU AI Act affect LLM deployment?
The EU AI Act, effective August 2026, imposes risk-based regulations on AI systems. High-risk applications require transparency, robustness, and human oversight. For LLMs, this means providers and deployers must document data provenance and ensure that training data complies with copyright and privacy laws, influencing where and how models are trained and deployed.
What is jurisdiction-aware routing?
Jurisdiction-aware routing is a technical architecture pattern where an intelligent gateway directs API calls to specific model instances based on the user's location or data classification. For example, a request from a German user containing PII might be routed to a self-hosted model in Frankfurt, while a generic query from a US user goes to a central API.
Is self-hosting LLMs too expensive for small businesses?
It can be. Self-hosting requires significant capital expenditure for GPUs and ongoing operational costs for maintenance. Small businesses often rely on managed services or specialized compliance platforms that offer multi-tenant, region-specific hosting. Alternatively, they may limit AI features to low-sensitivity tasks that can use standard APIs.
Do metadata and logs count as personal data?
Yes, increasingly so. Experts warn that metadata, such as IP addresses, timestamps, and usage patterns, can be combined to re-identify individuals. Therefore, logs generated by LLM interactions should be treated with the same care as the input data itself, ensuring they are stored and processed within the required jurisdiction.
john randall
August 10, 2026 AT 13:48Just reading through this and it makes sense. The API route is easy until it isn't.
Jeff Falcon
August 10, 2026 AT 17:39I have been working with these systems for a while now, and honestly, the shift towards self-hosting feels inevitable for anyone serious about compliance. It is not just about the fines anymore; it is about trust. When you hand your data off to a black box, you are gambling with your reputation. Sure, setting up the infrastructure takes time, but once it is done, you sleep better at night knowing exactly where every byte is sitting. The latency hit is negligible for most use cases anyway. People complain about the extra hundred milliseconds, but they do not realize that the alternative is getting shut down by regulators in Frankfurt or Beijing. It is a small price to pay for sovereignty. Plus, the cost curve flattens out pretty quickly if you have steady traffic. Why keep renting compute power when you can own the pipeline? It gives you so much more flexibility down the road too. You are not locked into someone else's roadmap or pricing model. It is just smarter engineering in the long run, even if the upfront headache is real.
Alyson Karson
August 11, 2026 AT 23:02omg yes! nobody talks enough about the metadata trap. like sure the text might be anonimized but the logs? those are goldmines for re-identification. i always tell my team to treat logs like PII because they basically are. its scary how many startups ignore this until its too late. we had a client almost get fined bc their failover went to a non-compliant region during a drill. classic mistake. self hosting is the only way to go if u want to stay safe. dont risk it!
Chris Neal
August 12, 2026 AT 15:25The article misses a crucial point about model quantization. Self-hosting Llama 3 on consumer-grade hardware is becoming viable thanks to 4-bit and 8-bit quantization techniques. You don't necessarily need massive GPU clusters for every deployment. For many enterprise internal tools, a single A100 or even a high-end RTX card can handle the load efficiently if optimized correctly. The "expertise" barrier mentioned is overstated for basic deployments. Docker containers with pre-built images make it accessible. The real issue is maintenance, not initial setup. Also, the claim that API providers retain usage data is often mitigated by enterprise agreements that explicitly forbid training on customer data. It's not all or nothing. Many large corps use APIs with strict DPAs and get away with it fine. The fear-mongering about "brief touches" of servers is exaggerated unless you are dealing with top-secret government intel. For general business, standard SLAs usually suffice.
Vishnu Vardhan Reddy M S
August 13, 2026 AT 23:34Oh look, another tech bro trying to convince everyone that APIs are fine because he read one PDF. Good luck explaining to the EU regulator that your 'enterprise agreement' covers the sub-sub-contractor who routed the packet through Virginia. We laugh because we've seen the audits. In India, we deal with DPDP Act which is getting stricter every month. If you think a DPA saves you from everything, you are living in a fantasy land. Self-hosting is boring, expensive, and hard. That is why it works. It forces you to care about your data. APIs are for people who want to move fast and break things, preferably other people's privacy laws.
Kyle Ware
August 15, 2026 AT 08:12its not about being right or wrong its about risk tolerance. if you are a startup with no revenue maybe api is fine. if you are handling health records self host. simple as that. dont overcomplicate it
Iva Grekova
August 16, 2026 AT 01:54I really appreciate this balanced view. It is easy to get overwhelmed by the regulations, but breaking it down by region helps a lot. I work in fintech and we are currently evaluating Mistral for our local deployment. The idea of jurisdiction-aware routing is fascinating. Have any of you actually implemented that kind of gateway logic? Seems complex to maintain two different infrastructures simultaneously. But I guess that is the new normal. Better safe than sorry, right?
Onyinyechi Nwosu
August 16, 2026 AT 20:49the disaster recovery part hit home. we lost a whole sprint fixing our failover configs after realizing they violated residency rules. nobody thinks about DR until something breaks. then you panic. make sure your backups stay in the same country as your primary. it costs more but saves headaches later
Chandan Singh
August 17, 2026 AT 18:16In my experience, the hybrid approach is the only realistic one for global companies. Pure self-hosting is unsustainable for scale, pure API is a compliance nightmare. The key is automated classification. You need ML models that classify incoming prompts for sensitivity in real-time before they hit the backend. If it contains PII, route to local instance. If generic, route to central API. This requires robust tagging and monitoring. Most teams fail here because they rely on manual reviews or static rules which are too brittle. Dynamic routing based on content analysis is the future. Also, do not underestimate the cost of egress fees if you are moving data between regions unnecessarily. Optimize your network topology early.
Brannen Hall
August 19, 2026 AT 08:00This whole post is just vendor hype for open-source solutions. APIs are getting better at localization. Every major provider now has regional endpoints that guarantee data stays put. The overhead of managing GPUs, cooling, and updates is a joke compared to the reliability of managed services. Companies are rushing to self-host because they think it looks cool, not because it is necessary. Most breaches happen due to human error, not server location. Stop creating problems to sell solutions.