Tag: vector database storage
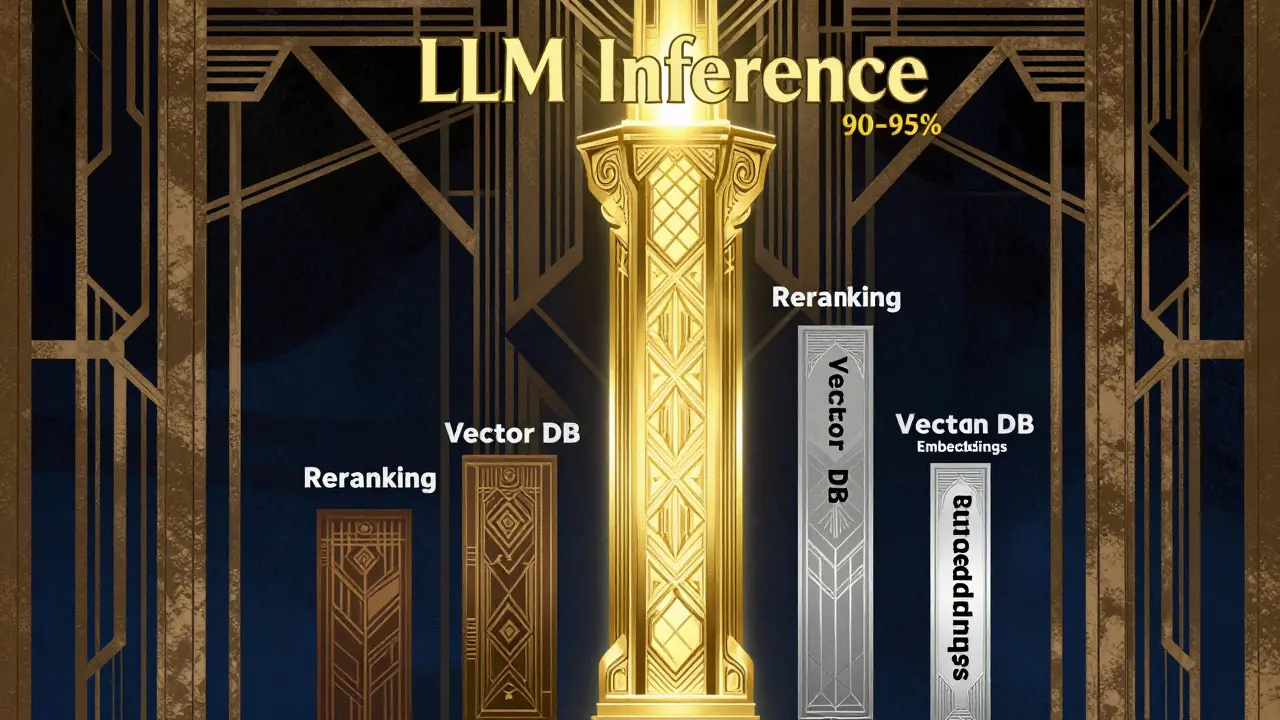
Cut RAG Costs: Optimize Embeddings, Storage, and Context Budgets

Cut RAG Costs: Optimize Embeddings, Storage, and Context Budgets

Discover how to cut RAG pipeline costs by optimizing LLM context budgets, embedding quantization, and vector storage. Learn why LLM inference dominates expenses and how to prioritize savings effectively.
Read More

Recent Post

  • Third-Party Risk in Generative AI: Vendor Assessments and Shared Responsibility

    Third-Party Risk in Generative AI: Vendor Assessments and Shared Responsibility

    Jul, 28 2026

  • Vibe Coding Security: What Buyers Must Assess Before Adopting AI Tools

    Vibe Coding Security: What Buyers Must Assess Before Adopting AI Tools

    Aug, 1 2026

  • AI Pair PM: How AI Agents Are Automating Product Requirements from Draft to Final

    AI Pair PM: How AI Agents Are Automating Product Requirements from Draft to Final

    Mar, 1 2026

  • Scaling Behavior Across Tasks: How LLM Performance Changes with Size

    Scaling Behavior Across Tasks: How LLM Performance Changes with Size

    Aug, 21 2026

  • Cutting LLM Agent Costs: Managing Tool Calls, Context Windows, and Think Tokens

    Cutting LLM Agent Costs: Managing Tool Calls, Context Windows, and Think Tokens

    Oct, 10 2026

Categories

  • Artificial Intelligence (255)
  • Cybersecurity & Governance (57)
  • Business Technology (13)

Archives

  • November 2026 (13)
  • October 2026 (32)
  • September 2026 (30)
  • August 2026 (32)
  • July 2026 (31)
  • June 2026 (31)
  • May 2026 (33)
  • April 2026 (29)
  • March 2026 (25)
  • February 2026 (20)
  • January 2026 (16)
  • December 2025 (19)

About

Artificial Intelligence

Tri-City AI Links

Menu

  • About
  • Terms of Service
  • Privacy Policy
  • CCPA
  • Contact

© 2026. All rights reserved.