Tag: RAG cost optimization
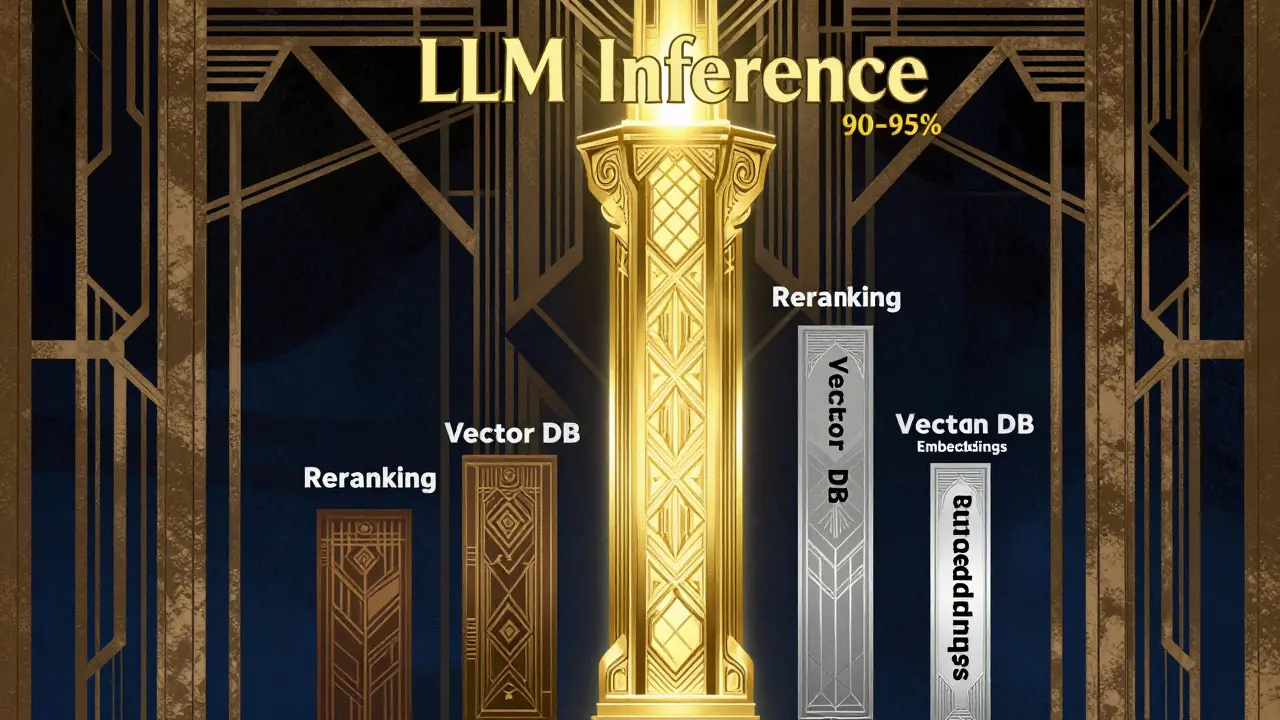
Cut RAG Costs: Optimize Embeddings, Storage, and Context Budgets

Cut RAG Costs: Optimize Embeddings, Storage, and Context Budgets

Discover how to cut RAG pipeline costs by optimizing LLM context budgets, embedding quantization, and vector storage. Learn why LLM inference dominates expenses and how to prioritize savings effectively.
Read More

Recent Post

  • Rapid Prototyping with APIs vs Production Hardening with Open-Source LLMs

    Rapid Prototyping with APIs vs Production Hardening with Open-Source LLMs

    Jun, 9 2026

  • Edge Inference for Small Language Models: When On-Device AI Wins

    Edge Inference for Small Language Models: When On-Device AI Wins

    Oct, 24 2026

  • Building an Evaluation Culture for LLM Teams: A Practical Guide

    Building an Evaluation Culture for LLM Teams: A Practical Guide

    Aug, 5 2026

  • Governance Policies for LLM Use: Data, Safety, and Compliance

    Governance Policies for LLM Use: Data, Safety, and Compliance

    Mar, 14 2026

  • Code Generation with Large Language Models: Capabilities, Risks, and Security in 2026

    Code Generation with Large Language Models: Capabilities, Risks, and Security in 2026

    Jul, 30 2026

Categories

  • Artificial Intelligence (255)
  • Cybersecurity & Governance (57)
  • Business Technology (13)

Archives

  • November 2026 (13)
  • October 2026 (32)
  • September 2026 (30)
  • August 2026 (32)
  • July 2026 (31)
  • June 2026 (31)
  • May 2026 (33)
  • April 2026 (29)
  • March 2026 (25)
  • February 2026 (20)
  • January 2026 (16)
  • December 2025 (19)

About

Artificial Intelligence

Tri-City AI Links

Menu

  • About
  • Terms of Service
  • Privacy Policy
  • CCPA
  • Contact

© 2026. All rights reserved.