Tag: GPU optimization
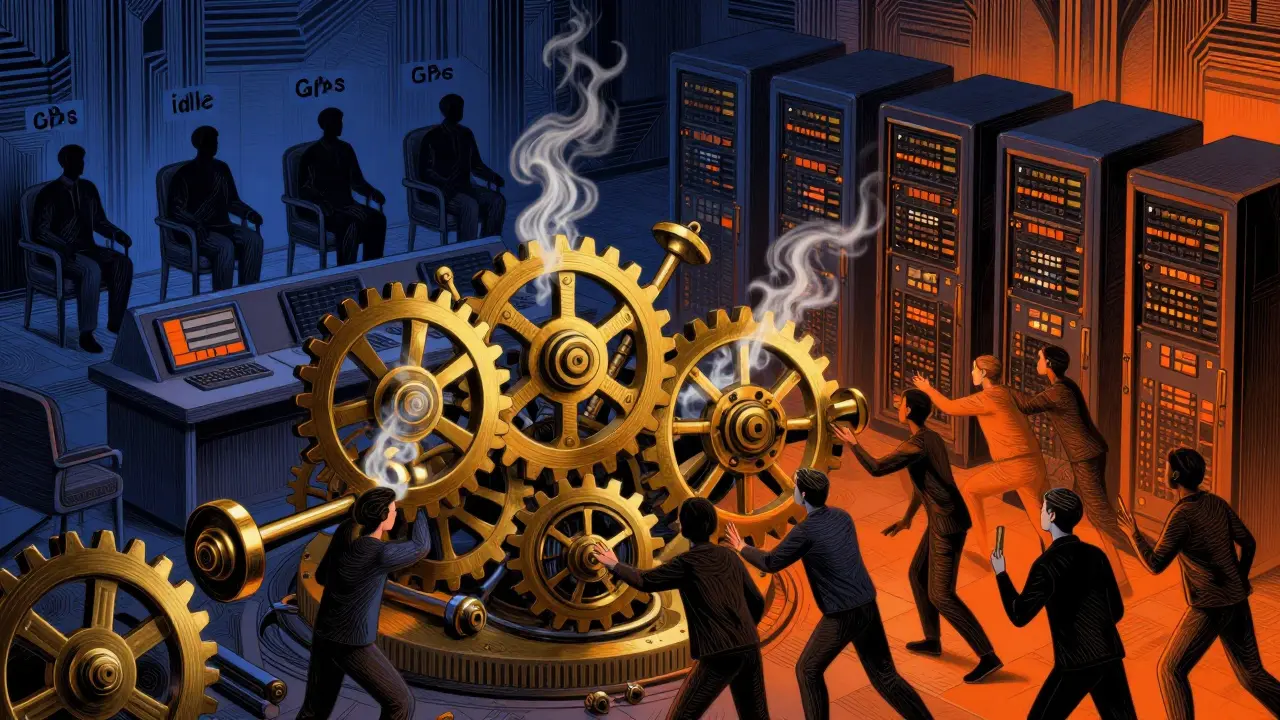
Cost-Aware Scheduling for LLM Workloads: A Practical Guide to Saving Money and Meeting SLAs

Cost-Aware Scheduling for LLM Workloads: A Practical Guide to Saving Money and Meeting SLAs

Learn how cost-aware scheduling optimizes LLM inference by balancing SLAs and GPU costs. Explore frameworks like DeepServe++ and CATP-LLM to cut expenses and improve latency.
Read More

Recent Post

  • Compress or Switch? A Practical Guide to Optimizing LLM Systems

    Compress or Switch? A Practical Guide to Optimizing LLM Systems

    Jul, 12 2026

  • How to Budget for Multimodal AI: Controlling Latency and Costs Across Modalities

    How to Budget for Multimodal AI: Controlling Latency and Costs Across Modalities

    Feb, 5 2026

  • Building a Vibe Coding Center of Excellence: Charter, Staffing, and Goals

    Building a Vibe Coding Center of Excellence: Charter, Staffing, and Goals

    Sep, 18 2026

  • Pair Reviewing with AI: How Human + Machine Code Reviews Boost Maintainability

    Pair Reviewing with AI: How Human + Machine Code Reviews Boost Maintainability

    Sep, 24 2025

  • Multimodal Agents in Generative AI: See, Hear, and Act

    Multimodal Agents in Generative AI: See, Hear, and Act

    Oct, 20 2026

Categories

  • Artificial Intelligence (246)
  • Cybersecurity & Governance (56)
  • Business Technology (13)

Archives

  • November 2026 (3)
  • October 2026 (32)
  • September 2026 (30)
  • August 2026 (32)
  • July 2026 (31)
  • June 2026 (31)
  • May 2026 (33)
  • April 2026 (29)
  • March 2026 (25)
  • February 2026 (20)
  • January 2026 (16)
  • December 2025 (19)

About

Artificial Intelligence

Tri-City AI Links

Menu

  • About
  • Terms of Service
  • Privacy Policy
  • CCPA
  • Contact

© 2026. All rights reserved.