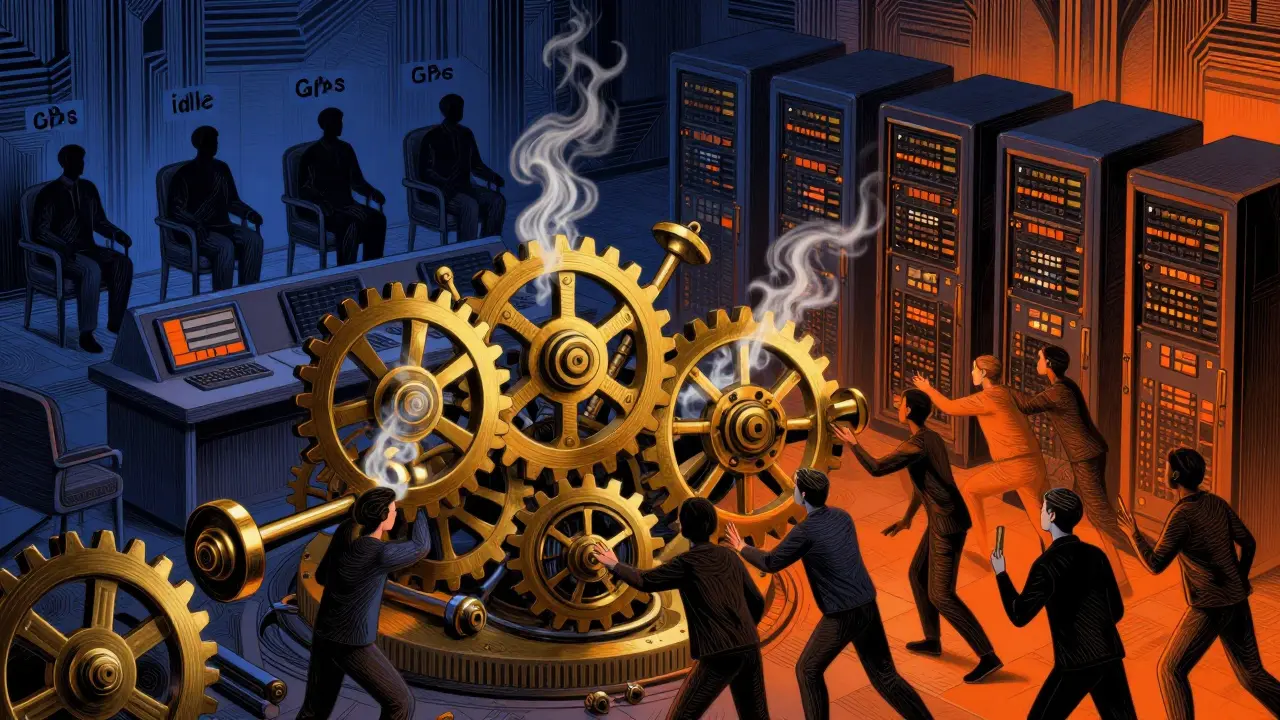
Tag: DeepServe++

Cost-Aware Scheduling for LLM Workloads: A Practical Guide to Saving Money and Meeting SLAs

Cost-Aware Scheduling for LLM Workloads: A Practical Guide to Saving Money and Meeting SLAs

Learn how cost-aware scheduling optimizes LLM inference by balancing SLAs and GPU costs. Explore frameworks like DeepServe++ and CATP-LLM to cut expenses and improve latency.

Read More

Recent Post

  • Accessibility in Generative AI: A Guide to Inclusive Design for All Users

    Accessibility in Generative AI: A Guide to Inclusive Design for All Users

    Jun, 4 2026

  • Mastering Dependency Management in Vibe-Coded Apps: Upgrade Safely

    Mastering Dependency Management in Vibe-Coded Apps: Upgrade Safely

    Mar, 27 2026

  • Compliance Controls for Vibe-Coded Systems: SOC 2, ISO 27001, and More

    Compliance Controls for Vibe-Coded Systems: SOC 2, ISO 27001, and More

    May, 6 2026

  • Human-in-the-Loop Evaluation Pipelines for LLMs

    Human-in-the-Loop Evaluation Pipelines for LLMs

    Sep, 15 2026
  • Rotary Position Embeddings (RoPE) vs ALiBi: Which LLM Positioning Method Wins?

    Rotary Position Embeddings (RoPE) vs ALiBi: Which LLM Positioning Method Wins?

    Apr, 15 2026

Categories

  • Artificial Intelligence (246)
  • Cybersecurity & Governance (56)
  • Business Technology (13)

Archives

  • November 2026 (3)
  • October 2026 (32)
  • September 2026 (30)
  • August 2026 (32)
  • July 2026 (31)
  • June 2026 (31)
  • May 2026 (33)
  • April 2026 (29)
  • March 2026 (25)
  • February 2026 (20)
  • January 2026 (16)
  • December 2025 (19)

About

Artificial Intelligence

Tri-City AI Links

Menu

  • About
  • Terms of Service
  • Privacy Policy
  • CCPA
  • Contact

© 2026. All rights reserved.